hungdv

Doan Viet Hung · AI / Computer vision engineer

I build computer vision systems that work outside the lab.

Computer vision engineer based in Vietnam. Industrial defect detection, face and license plate recognition, document OCR, and camera-based measurement.

Project details

Surface defect inspection with a line-scan camera

Private source

The anomaly detector learns only from good samples and needs no defect images. Each image returns OK or NOK, an anomaly map, a mask and boxes around suspect regions.

Results

Results on a 133-image test set (26 defective, 107 good). The README marks the latency figures as historical results.

Recall
24/26 (92.3%)
133 test images: 26 defective, 107 good
False alarms
3/107 (2.8%)
same test set
P50 latency
43 ms
RTX A4000, FP16, batch 15, 3,990 consecutive frames; P95 is 44 ms
On CPU
≈ 683 ms
OpenVINO FP32, 2 × Xeon Gold 6138

Problem

Defects are too rare and varied to collect for training, and the line needs a decision for every image within about 50 ms.

Approach

  • PatchCore on MobileNetV3-Large (FP16), with a memory bank built from only 10 good images.
  • Each 1024 × 1792 image is tiled, scored, merged into one anomaly map and thresholded on 50 separate good images.
More implementation details
  • Features come from blocks.4 and blocks.6. Tiles are 448 px with 0.20 overlap; the memory bank uses a 0.10 coreset.
  • Tile scores are blended with a Hann window, Gaussian-smoothed, normalized against good-image statistics and restricted to the ROI.
  • An operations dashboard built with aiohttp and React 19 (TypeScript, Vite, shadcn/ui) keeps history in SQLite and grabs frames from a Basler camera via pypylon. A Train & Setup tab lets operators create a product, upload good images, train and activate it from the browser.

Deployment lessons

  1. 1.An encoder-triggered line-scan camera only produces frames while the table turns. No frames while the motor is stopped is correct behaviour, not a network fault.
  2. 2.A camera cable routed through a PLC port runs at only 100 Mbps. Around 64 Mbit/s was fine; pushing the table speed toward 98 Mbit/s started dropping frames.
How it was evaluated

Few-shot experiments under a budget of 10 or 15 good images were run across 8 seeds with nested leave-one-out validation, giving 160 operating points.

Conclusions are recorded even when a new configuration does not help, for example: no configuration yet improves recall and the false-alarm rate at the same time. Keeping negative results stops the next attempt from repeating a dead end.

Full write-up of the few-shot studyTen good images are enough for the model, not for the threshold

Stack

  • PyTorch
  • PatchCore
  • MobileNetV3
  • FP16
  • OpenVINO
  • aiohttp
  • React 19
  • TypeScript
  • SQLite
  • pypylon

IntelliDoc OCR: digitizing Vietnamese administrative documents

Private source

The system takes PDFs, extracts content with OCR, lets a reviewer correct and approve each field, and keeps evidence so results can be audited later.

Results

Three processing modes; merged-dossier splitting with a human-confirmed boundary step; manual crops as evidence; an audit log.

Job tracking, OCR cost tracking and a System Monitor; VI/EN interface. Up to 15 PDFs per job, 200 MiB in total.

Pages processed
237
66 PDFs in 6 jobs, internal test run, Jul 2026
Failed pages
0
same run, after automatic retries
OCR calls
137/137
all succeeded with complete usage records
Fields with evidence
544/660
extracted fields with a bounding box and evidence crop (82%)

Status: Two milestones complete; in internal testing, not a customer-approved release. Field accuracy against ground truth has not been measured yet.

Problem

Documents come in many layouts, and when OCR is wrong a person must fix it in a way that stays traceable.

Approach

  • Next.js front end; FastAPI accepts jobs; Celery and Redis run the queue; Nginx sits in front; everything runs in Docker Compose.
  • The OCR endpoint is OpenAI-compatible and configured on the server; keys and URLs never reach the browser. External endpoints require an explicit confirmation.
More implementation details
  • Login uses hashed passwords and sessions signed with a secret key. Results are stored per job as JSON, PDF and artifacts; Redis is only the queue.

Stack

  • Next.js
  • FastAPI
  • Celery
  • Redis
  • Nginx
  • Docker Compose

Vision Measurement Toolkit: distance and speed from a camera

Open source · View the code on GitHub

A toolkit combining camera calibration, planar distance, 3D measurement from single-camera depth estimation, and lane-based vehicle speed.

Results

Three command-line apps: distance and height, realtime depth distance, and lane speed.

Two earlier experiment repos (Distance_calculation, Velocity_detection) were refactored into one tested package.

Geometric
49 FPS
13.34% MAPE on distance; homography + YOLO; Intel Core i7, GTX 1650 Ti
Deep learning
> 230 FPS
display rate, 15.07% MAPE; Depth Anything V2 in its own worker; same machine

Problem

Getting metres out of a 2D image means knowing how many metres one pixel covers, and that number changes with distance from the camera.

Approach

  • Road-plane-to-image homography; chessboard camera calibration; optical flow to keep the calibration stable.
  • YOLO for detection and Depth Anything for depth, each in its own worker so neither blocks the other. Targets are picked with a click and tracked with KCF.
More implementation details
  • The speed module ships with a script that checks results against ground-truth data.

Stack

  • OpenCV
  • Homography
  • YOLO
  • Depth Anything
  • KCF
  • Python

Workplace safety monitoring with a multi-stage pipeline

Private source

A six-stage pipeline detects and tracks people, then checks helmets, vests, face masks, gloves and behaviours such as phone use on a realtime video stream. A zone rule flags anyone who walks into a restricted area.

Results

The same code runs as a realtime web app, on RTSP streams and as a batch CLI.

PyTorch models are exported to ONNX and run with ONNX Runtime; the glove model runs as TFLite on CPU.

Status: Not yet evaluated quantitatively: no FPS or per-stage accuracy has been measured on fixed hardware.

Problem

Helmets and vests show in the full frame, but masks and gloves need face and hand crops; running every model on the full frame is slow and noisy.

Approach

  • Six stages: person detection and tracking → PPE (helmet, vest) → region split (head-face, hands, torso) → mask → gloves → behaviour.
  • Each person is cropped into regions before the matching classifier sees it. Mask and glove results are cached per track_id and refreshed periodically to save compute.
More implementation details
  • The PPE and behaviour branches run in parallel on the original frame and do not depend on the region split.
  • Restricted zones are polygons drawn on the camera view; a tracked person is flagged while standing inside one.

Stack

  • PyTorch
  • ONNX Runtime
  • TFLite
  • Tracking
  • RTSP

Helmets and vests on a factory floor

Pipeline output on a public YouTube clip, not a client site.

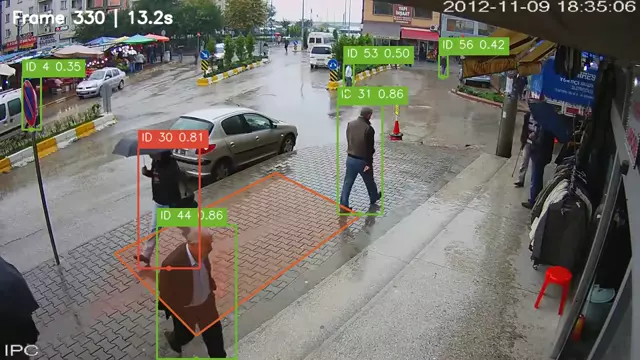
Restricted zone

Street CCTV from a public YouTube clip. A person turns red while inside the orange zone.

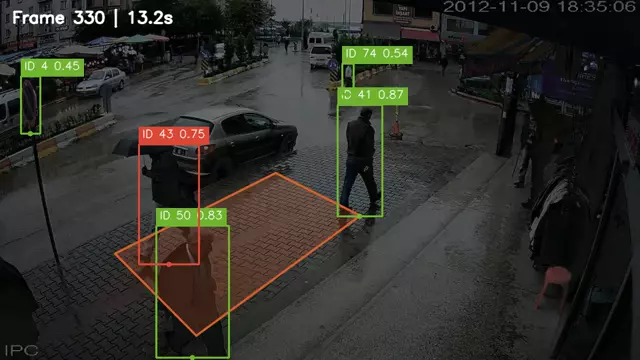
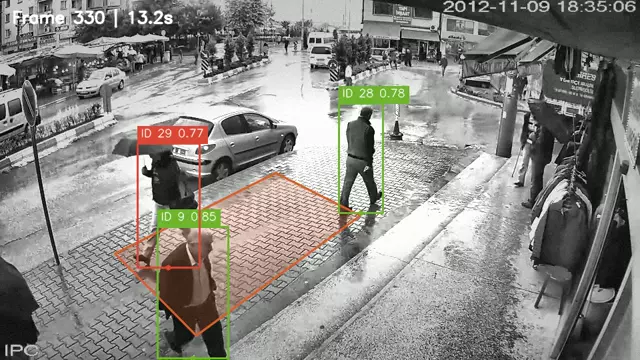
Same frame, three lighting conditions

  • OriginalOriginal
  • Darkened (night)Darkened (night)
  • Greyscale (IR)Greyscale (IR)
The darkened and greyscale versions were made from the same clip to test robustness. The zone alert still fires in all three, but the track ID differs (30, 43, 29), so tracking is not identical across conditions.

Areas of work

Beyond the four projects above, I work on the following problems.

Face recognition
Selecting and benchmarking detectors, landmark models and embeddings for real deployment conditions.
Face anti-spoofing
Telling a live face from a printed photo or a replayed screen before recognition.
License plate recognition (ALPR)
Benchmarks on Vietnamese plates and multi-camera pipelines.
Industrial anomaly detection
Learning from good samples and running within production-line time budgets.

Research interests

Questions I ran into while deploying systems and want to study further:

  1. Q1How reliable can anomaly detection be with only a handful of good images, and how do we evaluate it honestly under such a small data budget?
  2. Q2How should an operating point between recall and false alarms be chosen and maintained as production data drifts over time?
  3. Q3What does a face anti-spoofing model need to generalize across camera types and attack devices it never saw in training?
  4. Q4How accurate can measurement from a single camera be, and how should its uncertainty be estimated and reported?

Experience

HPT Vietnam Corporation

  • Intern · Jul 2025 – Nov 2025
  • AI – Computer Vision Solution Engineer · Dec 2025 – present
  • Contributed to the company's vision AI platform for security and operations: face recognition, face anti-spoofing, license plate recognition (ALPR) and PPE detection. Co-author on the platform's intellectual property certificate.
  • Designed and deployed AI surveillance proof-of-concept systems on multi-stream RTSP (H.264) camera feeds, running on NVIDIA GPU edge devices.
  • Optimized realtime inference pipelines with ONNX Runtime and CUDA, reducing latency and keeping multi-stream processing stable under hardware constraints.
  • Containerized models and backend services with Docker for reproducible on-premise deployment at enterprise clients, including major food and beverage brands.
  • Worked directly with stakeholders to turn business requirements into system-level AI architectures, balancing accuracy and latency for each real-world use case.

Education

University of Science, Vietnam National University Ho Chi Minh City

BS in Computer Science, major in Computer Vision · Oct 2021 – Oct 2025

Languages: Vietnamese (native), English (professional working proficiency).

Achievements and certifications

  • Co-author, intellectual property certificate for a vision AI platform for security and operations.
  • Certificate: Getting Started with Deep Learning.

Contact

If you need someone who takes computer vision from experiment to deployment, or want to talk about the research questions above, get in touch.